FAQ
Why use this API? Why not just use plain Cypher?
Cypher is a powerful language for querying the neuprint database, and there will always be some needs that can only be satisfed with a custom-tailored Cypher query.
However, there are some advantages that come from using the higher-level
API provided in neuprint-python:
To use Cypher, you need an understanding of the neuprint data model. It’s not too complex, but for many users, basic neuron attributes and connection information is enough.
Some queries are difficult to specify. For example, efficiently filtering neurons by
inputRoioroutputRoiis not trivial. ButNeuronCriteriahandles that for you.The
neuprint-pythonAPI uses reasonable default parameters, which aren’t always obvious in raw Cypher queries.neuprint-pythonsaves you from certain nuisance tasks, like convertingroiInfofrom JSON data into a DataFrame for easy analysis.When a query might return a large amount of data, it’s often critical to break the query into batches, to avoid timeouts from the server. For functions in which that is likely to occur,
neuprint-pythonimplements batching for you.
Nonetheless, if you need to run a query that isn’t conveniently
supported by the high-level API in this library,
or you simply prefer to write your own Cypher,
then feel free to use Client.fetch_custom().
What Cypher queries are being used by this code internally?
Enable debug logging to see the cypher queries that are being sent to the neuPrint server.
See setup_debug_logging() for details.
Where are the release notes for the data?
Please see the neuprint dataset release notes and errata.
Where can I find general information about the FlyEM Hemibrain dataset?
See the hemibrain description page.
I want to analyze the whole connectome. Can I download it instead of querying neuprint?
Yes, and please do! The neuprint server is designed for interactive exploration and
targeted queries (a few cell types, a circuit, a region), not for exporting the entire dataset.
If you need all neurons, all connections, all synapses, or all skeletons in a dataset
(e.g. for whole-connectome analysis, graph statistics, simulation, or machine learning),
download the bulk exports instead of looping over fetch_neurons(), fetch_adjacencies(),
fetch_synapses(), fetch_skeleton(), or fetch_custom().
The bulk files are faster to obtain, easier to work with, and they don’t burden the shared
neuprint server for other users.
Bulk exports for the major FlyEM datasets are stored in public Google Cloud Storage buckets:
Dataset |
Bulk downloads |
|---|---|
male-cns |
See the male-cns download page. |
optic-lobe |
|
MANC |
|
hemibrain |
|
The bucket contents and file naming conventions differ from one dataset to the next, so look for a README in the bucket (or on the dataset’s download page). The dataset descriptions shown on the neuprint website also link to the relevant bucket.
The “browse” links above require a Google login, but the buckets are public, so no login is needed to list or download their contents. For example:
# List the contents of a bucket directory with the gcloud CLI
gcloud storage ls gs://hemibrain/v1.2/

# ...or without any tools, via the public JSON API
curl 'https://storage.googleapis.com/storage/v1/b/hemibrain/o?prefix=v1.2/&delimiter=/'

# Download an individual file via plain HTTPS
curl -O https://storage.googleapis.com/hemibrain/v1.2/exported-traced-adjacencies-v1.2.tar.gz
Note
For datasets not listed here, check the dataset’s description on the neuprint website. If you still can’t find a bulk download, please ask on the neuPrint Google Groups forum before attempting to export the whole dataset through the neuprint API.
How can I download the exact Hemibrain ROI shapes?
A volume containing the exact primary ROI region labels for the hemibrain in hdf5 format can be found here. Please see the enclosed README for details on how to read and interpret the volume.
Note
The volume tarball is only 10MB to download, but loading the full uncompressed volume requires 2 GB of RAM.
Can this library be used with multiprocessing?
Yes. neuprint-python’s mechanism for selecting the “default” client will automatically
copy the default client once per thread/process if necessary. Thus, as long you’re not
explicitly passing a client to any neuprint queries, your code can be run in
a threading or multiprocessing context without special care.
But if you are not using the default client, then it’s your responsibility to create
a separate client for each thread/process in your program.
(Client objects cannot be shared across threads or processes.)
Note
Running many queries in parallel can place a heavy load the neuprint server. Please be considerate to other users, and limit the number of parallel queries you make.
Where can I find help?
Please report issues and feature requests for
neuprint-pythonon github.General questions about neuPrint or the hemibrain dataset can be asked on the neuPrint Google Groups forum.
For information about the Cypher query language, see the neo4j docs.
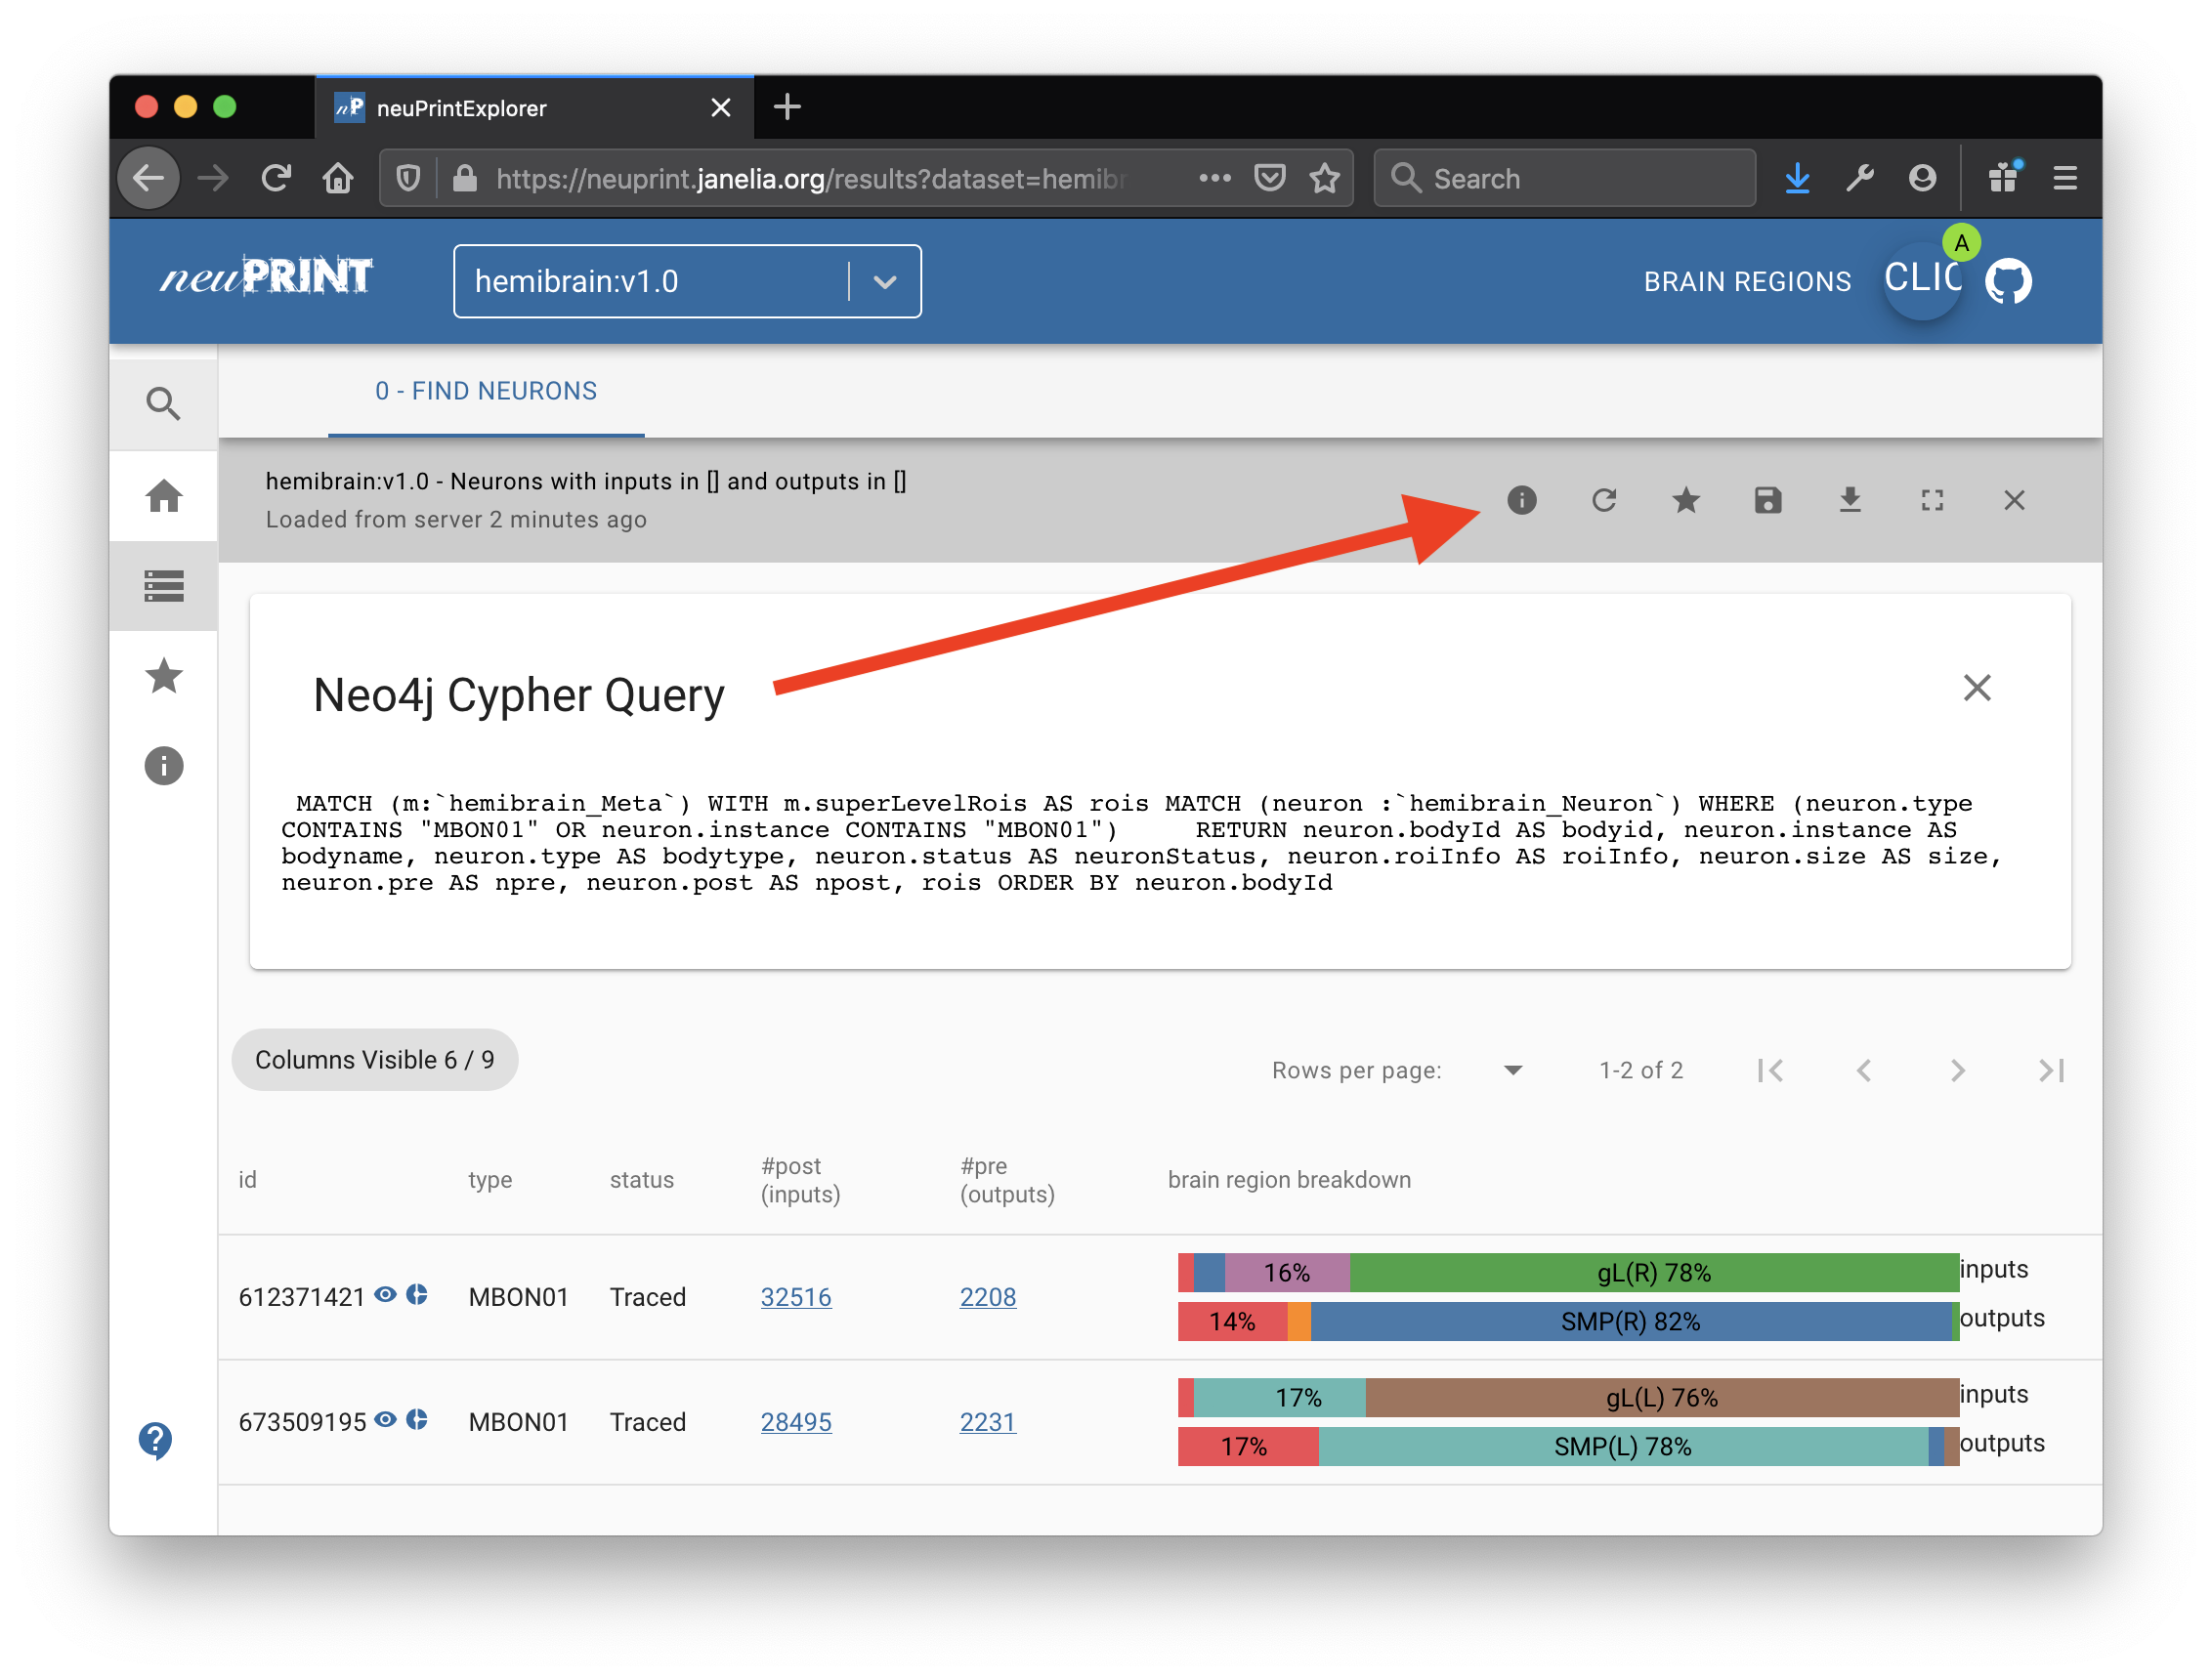
The best way to become acquainted with neuPrint’s capabilities and data model is to experiment with a public neuprint database via the neuprint web UI. Try exploring the Janelia FlyEM Hemibrain neuprint database. To see the Cypher query that was used for each result on the site, click the information icon (shown below).